The same harness that runs as a desktop app can serve a room full of people. A host loads the model once and runs one session per browser, each with its own context, its own agents and its own memory, over the one resident copy of the weights. You pay for the machine, not per token.
When to use it
| You want | Use |
|---|---|
| Several people using one model on one machine — an office appliance, a GPU box | The host (this page): npm run serve |
| One person, offline, on their own machine | The desktop app — Ship a desktop app |
| Every connection isolated in its own OS process | @lloyal-labs/relay — see Isolate by process |
Quickstart
npm run serveserve builds the harness and starts the host. It downloads and verifies any model it still needs before it listens, so no browser ever waits on a download, and then prints that it is listening. In another shell, start the browser app:
npm run dev:web:clientnpm run dev:web starts both together, which is what you want while developing.
Shared weights, separate session state
npm run serve runs sessions in one host process. Each reader gets a separate native llama_context over the same resident llama_model. Creating another context reuses the model's weights.
The OS analogy is direct: resident weights play the role of shared, read-only pages; each session's KV tree is its private address space. The host multiplexes sessions over those weights, and agents fork within their session's space.
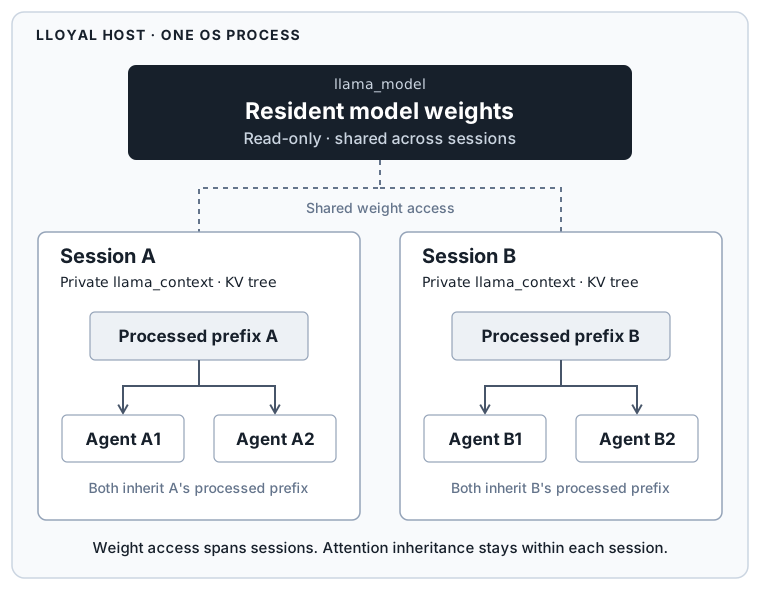
At boot, the host prepares the model and service files on disk before it listens. Native contexts and service bindings are created as sessions are admitted.
| Resource | Ownership in the host |
|---|---|
Model weights (llama_model), including the reranker |
Shared by contexts using the same model file and model-loading settings |
| KV cache and model-specific recurrent state | Separate for each reasoning or service context |
| Context compute buffers | Allocated for each context |
| Service bindings | Created and owned per session, using the files prepared at boot |
Vision projector (mtmd_context) |
Loaded per session, with its own projector weights and working buffers |
Additional readers consume context, service and projector memory while reusing the resident reasoning-model and reranker weights. Sharing weights does not share a reader's attention history with other readers. Agents can inherit attention within their own session's lineage, as described in Continuous Context.
Configure the box
What describes the machine comes from its environment, never from harness.yml: one build serves many machines.
| Variable | Default | What it sets |
|---|---|---|
PORT |
8787 |
The port the host listens on |
HOST |
127.0.0.1 |
The interface it binds. The host has no authentication of its own, so serving every interface (0.0.0.0) is an explicit choice — put it behind something that does authenticate. |
MAX_SESSIONS |
4 |
How many sessions may be resident at once. The rest wait their turn. |
LLOYAL_CONTENT_ORIGIN |
— | A web origin on another host allowed to upload files. Pages the host serves itself, or reaches through a proxy that sets X-Forwarded-Host, upload without it; an upload from any other site is refused. |
LLOYAL_DEV |
— | 1 turns on the trace and the dev pane per session |
HOST=0.0.0.0 PORT=8787 MAX_SESSIONS=8 npm run serveSize MAX_SESSIONS
A session holds its context and its service bindings for as long as its browser tab is open, even when the reader is idle. Budget for shared reasoning-model and reranker weights plus each session's KV/recurrent state, compute buffers and service working memory. When vision is configured, include each session's projector weights and working buffers too.
The cap is how many open sessions the machine can hold, not how many can work at once. Four is a cautious default for one machine, not a measurement. Measure with the model, context length and vision settings you actually deploy, with the sessions idle, and set it on the box.
What a reader sees
Sessions are admitted first come, first served. A browser moves through connecting → queued → warming → ready, and a view reads that with useAvailability() (see The interface) to say "you're in the queue" rather than look broken.
- A session is isolated. A harness that throws, or a service that fails to bind, ends that session alone, says why in the host's log, and the host keeps serving.
- A finished session closes its socket, so a browser can tell "the session ended" from "the network dropped".
- Visitors never change the harness. A setting saved from a browser applies to that session, in memory only. Nothing a visitor does relaunches the host, downloads a model or writes the configuration.
Point the browser at a host
The web app connects to ws://127.0.0.1:8787 unless told otherwise:
| To point it at | Set |
|---|---|
| A host fixed at build time | VITE_WSS_URL=wss://your.host/… when building the web app |
| A host chosen at run time | ?server=wss://your.host/… on the page's URL |
Isolate by process
@lloyal-labs/relay provides one harness process per connection. It starts your harness's bin in a separate Node process and relays its frames over the socket, putting an OS-process boundary between readers.
The model registry is process-local. Relay children therefore own separate model objects and context allocations; the relay does not share one llama_model or GPU allocation across those processes. The OS may share memory-mapped model-file pages, but that is separate from the host's shared model residency. Multiple llama_context instances within the host process reuse the same weights as described above.
The relay ships as a bridge you mount in your own server (Express, Hono, Koa…). No scaffold command wires it up yet. Use it when you need an OS-process boundary, and expect to write the server around it. Use npm run serve for the shared-residency host.
Related
- Where a harness runs — surfaces, placements and the Rails analogy.
- Choose where the work lives — run one build against a data folder elsewhere.
- The interface — the browser side of the socket.